I wanted different LLM providers behind one easy OpenCode setup: a truly sovereign European option, a powerful cheap one that is trustworthy enough for open-source work, and — in the future — a confidential one. The result is a gist I maintain: dhcgn/206f9adc367b6203c42841e12b726203.
Problem
Switching models between providers means editing config files, managing keys, and re-registering MCP servers per machine. I wanted one portable opencode.jsonc I can install with a single command and that covers my three trust tiers.
Prerequisites
- OpenCode installed (opencode.ai)
- PowerShell on Windows (one-line installer below;
curlvariant in the gist for bash) - API keys, set as user environment variables (never stored in the config file):
LYCEUM_API_KEY,META_API_KEYCONTEXT7_API_KEY,BRAVE_API_KEY,GITHUB_MCP_PAT
- Node.js with
npx(required by the local Brave search MCP server)
Steps
Install with cache-busting so you always get the latest gist revision:
irm "https://gist.githubusercontent.com/dhcgn/206f9adc367b6203c42841e12b726203/raw/Install-OpenCodeConfig.ps1?prevent_cache=$([guid]::NewGuid())" | iexThe script downloads opencode.jsonc, .env.example, and Set-OpenCodeEnvironment.ps1 to ~/.config/opencode/, then checks your user environment variables and prints SET / MISSING per name (never a value). Fill the missing ones into .env and apply with Set-OpenCodeEnvironment.ps1.
What the config contains
General settings: lsp enabled, the built-in opencode provider disabled, and the @dietrichgebert/ponytail plugin loaded.
Providers
| Tier | Provider | Models | Note |
|---|---|---|---|
| 🟢 Sovereign EU | Lyceum (German-based, OpenAI-compatible) | moonshotai/kimi-k3, z-ai/glm-5.3, z-ai/glm-5.3-flash | High data privacy from an EU perspective; 1M context / 131k output per model; low/high/max reasoning variants |
| ☢️ Cheap, OSS-safe | Meta Model API (US hyperscaler, not sovereign) | muse-spark-1.3-contributor, muse-spark-1.3 | Text+image+PDF+video input; use the contributor model only with public code and prompts — its lower price is tied to data being usable for learning |
| 🔜 Confidential | privatemode.ai, by Edgeless Systems (planned) | glm-5.3, kimi-k2.6, gpt-oss-120b | TEE-based inference with remote attestation and operator exclusion (Betreiberausschluss); OpenAI-compatible endpoints; not in the config yet — see below |
MCP servers and extras
| Server | Type | Purpose |
|---|---|---|
context7 | remote | Library documentation |
brave-search | local (npx) | Web search |
github | remote | GitHub Copilot MCP |
Plus Export-OpenCodePricing.ps1, which exports the config’s cost fields to pricing.csv.
Why privatemode.ai is next
Privatemode (docs v1.55, Sep 2026) runs inference inside attested confidential VMs: data stays encrypted in transit, at rest, and during use, and remote attestation lets the client verify what it talks to — so even the operator is technically excluded. That is the tier for confidential code, above sovereign (Lyceum) and public-only cheap (Meta contributor).
The candidate chat models, all with streaming, tool calling, and structured outputs (what an agent loop needs) on OpenAI-compatible endpoints (/v1/chat/completions etc.), so wiring follows the same pattern as the Lyceum entry:
| Model ID | Input | Context | Note |
|---|---|---|---|
glm-5.3 (glm-latest) | text | 256k tokens | Reasoning always on; low/high/max effort |
kimi-k2.6 (kimi-latest) | text, image | 256k tokens | Reasoning can be disabled via thinking: false |
gpt-oss-120b | text | 128k tokens | Smallest input price of the three |
Also available on the same platform: qwen3-embedding-4b embeddings and whisper-large-v3 / voxtral-mini-3b speech-to-text (the pair my hushscribe already uses).
Verification
- Confirm
~/.config/opencode/opencode.jsoncexists after install. - Re-run the installer — all variables should print
SET. - Start OpenCode and check the model picker shows the 🟢/⚠️/☢️ entries.
Costs
Relative prices are recorded in the config’s cost fields (state: Sep 2026): on Lyceum, glm-5.3-flash is cheapest and kimi-k3 highest; on Meta, the contributor model is a fraction of the regular one. Check the provider dashboards for current billing — the Lyceum pricing link is in the config comments.
Privatemode list prices for comparison (per 1M tokens, +VAT, Sep 2026): gpt-oss-120b €0.43 in / €1.70 out, glm-5.3 and kimi-k2.6 €1.55 / €7.74 with €0.15 cached input. So confidential does not mean expensive here — gpt-oss-120b undercuts the regular Meta model.
Intelligence vs. cost per task (13 Sep 2026, Artificial Analysis coding index) for the models in this post:
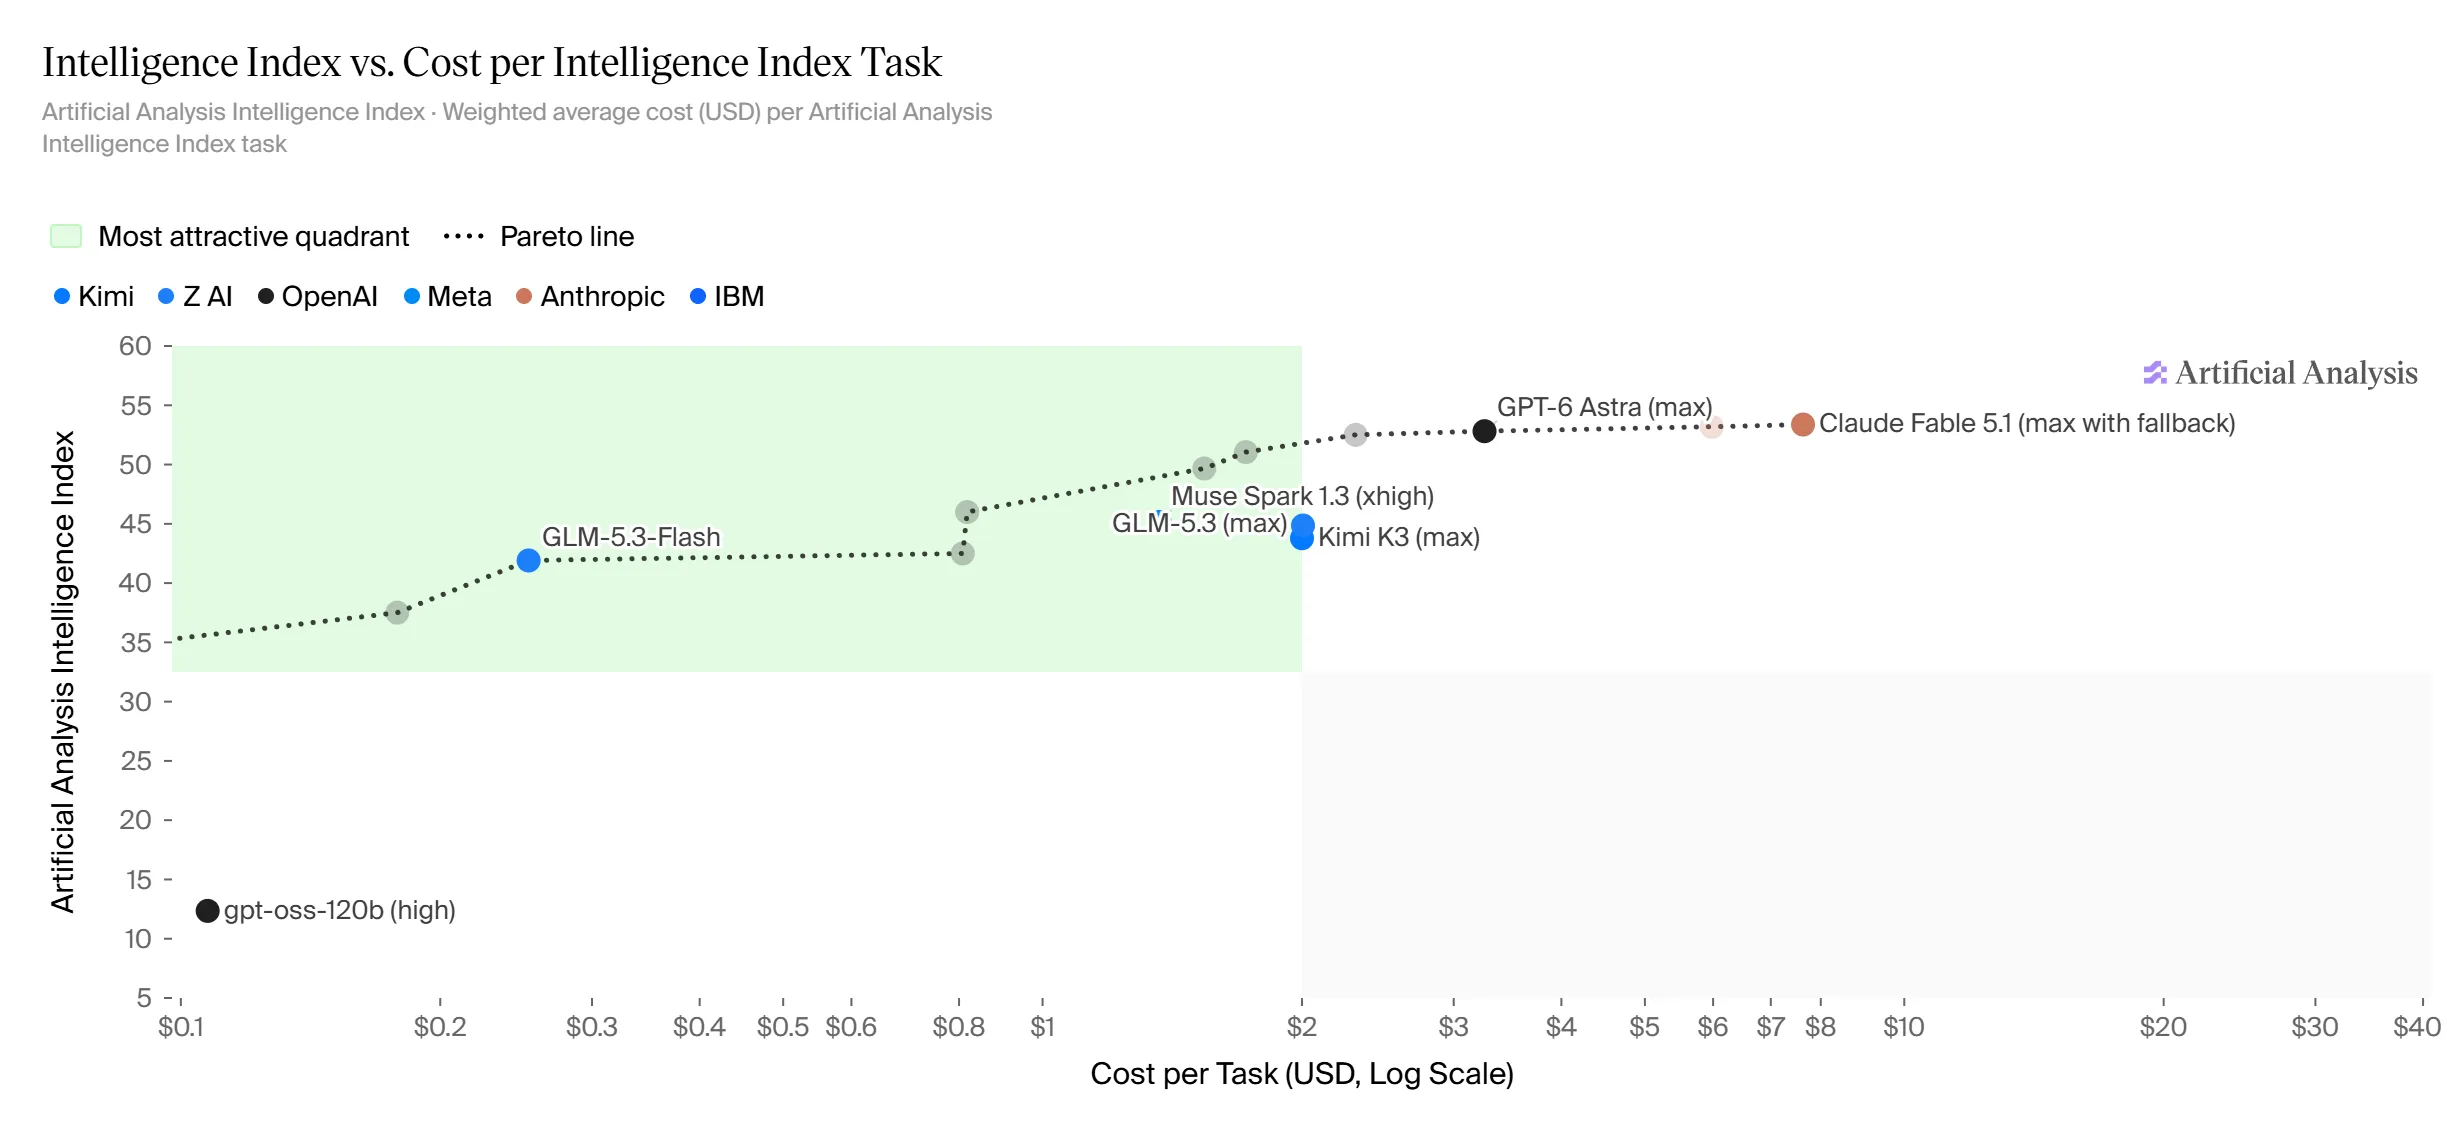
Source: Artificial Analysis intelligence vs. cost comparison — screenshot dated 13 Sep 2026, values rot fast.
Limitations
- The contributor model must never see private code or prompts.
- Meta is a US hyperscaler: cheap and multimodal, but not a sovereignty answer.
- Lyceum prices and model availability can change; the gist pins what I use, not a price guarantee.
- privatemode.ai support is outlook only — planned for confidential work where even the operator must be technically excluded.